Frontier AI Intelligence & Computing Infrastructure
Tracking next-generation foundation models, empirical autonomous agent benchmarks, open-weights architectures, and distributed GPU superclusters. Built for engineers, researchers, and systems architects.
Local LLM GPU VRAM Sizing Preview
Select a foundation model architecture to instantly calculate theoretical weights, KV cache overhead, and matching workstation graphics hardware.
Frontier Intelligence & Architecture
Peer-reviewed technical deep dives into model training mechanics, inference economics, and distributed systems.
From Amazon S3 to Distributed GPU Clusters: The 20-Year Evolution of Cloud AI
Tracing the architectural lineage from Jeff Barr's foundational 2006 S3 address at InfoIsland to modern 32,000-accelerator NVLink superclusters and custom silicon.
DeepSeek-V3 & R1: Open Weights Architectural Audit & Economics
How Multi-Head Latent Attention (MLA), DeepSeekMoE, DualPipe, and pure reinforcement learning disrupted proprietary frontier AI pricing by 95%.
AI in Computational Healthcare: Open Access Research & Medical LLMs
How 2006 consumer health information grants evolved into on-premise clinical foundation models, vector search over PubMed, and 94% diagnostic concordance.
Claude 3.7 / 4 Sonnet: Extended Thinking & Hybrid Reasoning Deep Dive
Anthropic's dynamic reasoning budget engine: balancing sub-second conversational latency against extended multi-turn coding test-case verification.
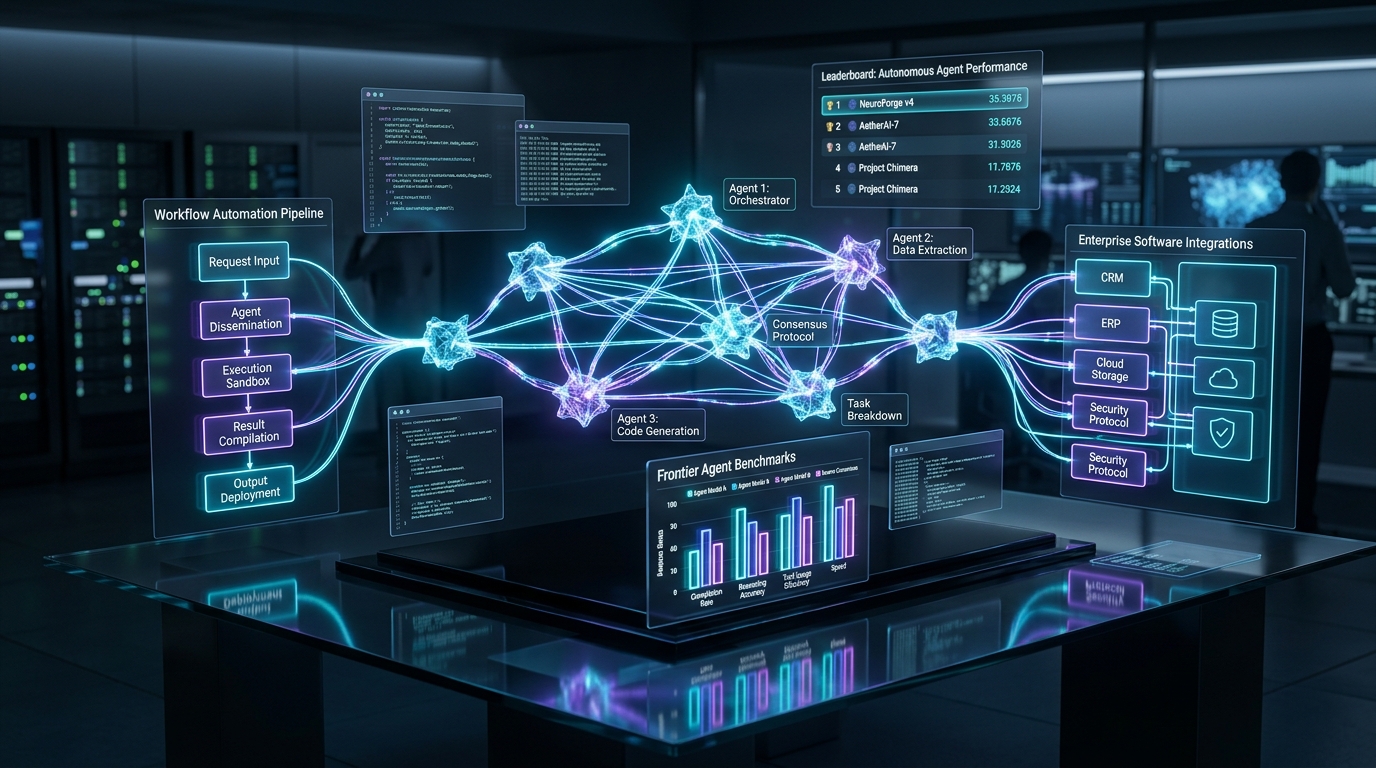
Autonomous AI Agents in Enterprise Workflows: The Economic Transition
The transition from human 3D avatar teleoperation in 2007 to autonomous LLM multi-agent swarms executing software refactors with 150x cost efficiency.
GPT-5 (Orion) Architecture, Release Timeline & Benchmark Rumors
Breaking through the pre-training data exhaustion wall: hierarchical mixture-of-experts, process supervision, and projected SWE-bench verified capabilities.
Zero-Latency Engineering Calculators
Execute hardware feasibility and API cost estimations directly in your browser with zero server telemetry.
LLM GPU VRAM & Local Hardware Calculator
Compute precise memory allocation for model weights, KV cache, and CUDA runtime across 1.5B to 671B parameter models with GGUF quantization (FP16 down to IQ2_XXS).
Frontier API Pricing & Token Cost Estimator
Model your monthly inference invoice side-by-side across OpenAI, Anthropic, Google Gemini, and DeepSeek with dynamic prompt caching discounts and reasoning token buffers.
Trending AI GitHub Deployment Guides
Terminal-ready blueprints for deploying open-source models, high-concurrency inference engines, and multi-agent systems.
Deploying DeepSeek-R1 / V3 Locally with Ollama & Open WebUI
Run distilled reasoning models on Windows & Linux with complete privacy. Includes GGUF quant selection, GPU layer offloading, and Dockerized WebUI setup.
High-Throughput Local Inference with vLLM & PagedAttention
Scale local serving throughput by 10x using PagedAttention memory management, continuous request batching, tensor parallelism, and OpenAI-compatible endpoints.
Building Production Multi-Agent Systems with CrewAI & LangGraph
Architect resilient multi-agent swarms with state graphs, conditional routing, cyclic execution verifiers, and isolated execution containers.
Chartered in October 2006, InfoIsland.org began as an internationally cited virtual research archipelago created by academic, medical, and technology librarians. Today, it stands as an authoritative technical publication preserving that 20-year unbroken heritage—maintaining historical citations from Amazon AWS, the National Diet Library of Japan, the American Library Association, and the University of Delaware, while advancing the frontiers of synthetic reasoning, agent autonomy, and distributed computing.